Incrementality Testing for Ecommerce: Prove Ads Drive Sales
- Incrementality testing measures the sales your ads caused, not the sales that merely happened while the ad was running; attribution measures the second and calls it the first.
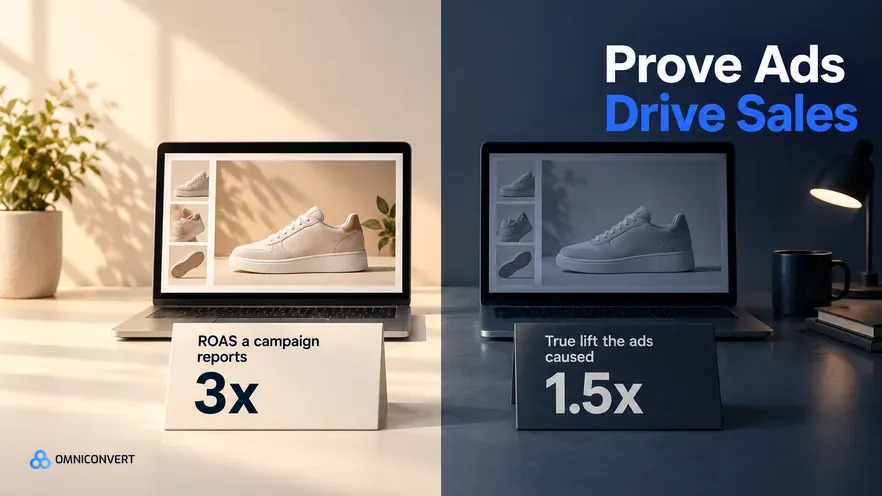
- Platforms routinely over-attribute by 20 to 60 percent, so a campaign showing 3x ROAS can deliver closer to 1.5x once you remove buyers who would have converted anyway.
- The method is a treatment-versus-holdout comparison, the same counterfactual logic as A/B testing, applied to media budget rather than page variants.
- Attribution collapsed for a reason: iOS ATT wiped out most mobile ad-ID matches and multi-touch coverage fell from over 90 percent to roughly 30 to 60 percent, so modelled credit replaced measured causation.
- Google cut its incrementality-test minimum to 5,000 dollars in 2025, so a structured holdout is now within reach of mid-market brands, not just enterprises.
Incrementality testing is a controlled experiment that measures the sales an ad actually caused, by comparing people who saw it against a matched group who did not. It exists because platform dashboards answer a narrower question than they appear to: whether an ad was present when a sale happened, not whether the ad made the sale happen. Those are different questions, and the gap between them is expensive. Across the 70,000+ controlled experiments in the CROBenchmark dataset, the discipline that separates the two is the same one that lifts conversion rates by an average of 23.2% [CROBenchmark Report 2026, Omniconvert].
Nexus by Omniconvert is the AI eCommerce growth engine that brings that controlled-experiment logic to media and on-site decisions. This guide covers why your ROAS dashboard misleads, what incrementality testing is, why attribution has collapsed, the four core methods, how to run your first test, how to read the result, and why incrementality is simply A/B testing pointed at media spend. Each section answers its question directly, then goes deeper.
Your ROAS dashboard measures the wrong thing
There is a name for what goes wrong here. Goodhart's Law states that when a measure becomes a target, it ceases to be a good measure. The moment return on ad spend became the number every campaign optimized toward, platforms learned to maximize claimed conversions rather than caused ones. Retargeting re-serves ads to people already walking to the checkout. Last-click credit rewards whichever touchpoint sat closest to a purchase that momentum had already made inevitable. The dashboard is not lying; it is answering the question it was built to answer, which is not the question you are asking.
It is also a case of the streetlight effect, the old story of the man searching for his keys under a lamppost, not because he dropped them there but because that is where the light is. Attribution measures the click and the pixel because they are easy to observe, not because they are where causation lives. Incrementality testing is the decision to look where it is dark: at the buyers you never showed the ad to, and what they did anyway.
What is incrementality testing?
The intellectual core of the method is the counterfactual. Every marketing decision rests on an unanswerable-looking question: what would have happened anyway? A treatment-versus-holdout design answers it by construction. You withhold the ad from a comparable group, watch what they do, and treat their behavior as the baseline the ad had to beat. The lift over that baseline, and only the lift, is what the ad caused.
Two terms make the rest of the article precise. Incremental lift is defined as the additional conversions in the exposed group beyond what the matched holdout produced on its own, expressed as a percentage of the holdout's rate. Incremental ROAS (iROAS) is defined as incremental revenue divided by ad spend, the honest cousin of the platform ROAS that counts only revenue the ad actually generated. A campaign can post a 3x attributed ROAS and, once the holdout is subtracted, deliver an iROAS closer to 1.5x, because platforms over-attribute by an estimated 20 to 60 percent [Triple Whale, 2026].
Why now: attribution is collapsing
The signal-loss story is not a rounding error. Apple's iOS 14.5 ATT prompt wiped out an estimated 75 to 85 percent of mobile ad-ID matches, with opt-in rates stuck near 25 percent [Prescient, 2026]. Multi-touch attribution, which once claimed to see more than 90 percent of the path to purchase, now observes closer to 30 to 60 percent of it [Measured, 2026]. The rest is filled by modelling, which is a polite word for an educated guess.
The barrier to running the alternative has fallen at the same time. At Google Marketing Live in May 2025, Google cut its incrementality-test minimum from 100,000 dollars to 5,000 dollars, a change enabled by a shift to Bayesian methods that reach a confident read on far less data; studies can run as short as 7 days, with 14 or more recommended [PPC Land, 2025]. A method that was once an enterprise luxury is now a mid-market practice, arriving precisely as the dashboards it replaces lose their sight.
The four core methods
The reason more than one method exists is selection bias: platforms deliberately show ads to the people most likely to buy, then take credit for the purchase. Ghost-ad designs exist specifically to strip that bias out by comparing the exposed group against the people the algorithm would have served. The table below is the plain-English version.
| Method | How the holdout is built | Best for | Watch out for |
|---|---|---|---|
| Geo-holdout | Pause or vary spend in matched regions, compare against control regions | Total-budget and channel-level decisions | Needs comparable regions and enough regional conversions |
| Ghost ads | Control group sees a placeholder; you compare users the algorithm would have targeted | Removing targeting selection bias | Requires platform support to implement cleanly |
| PSA / placebo test | Control group is served an unrelated public-service ad instead of yours | Simple exposed-versus-unexposed reads | Placebo ad still costs delivery budget |
| Platform conversion-lift | Meta, Google, or TikTok split traffic and report lift for you | Fast, low-setup reads inside one channel | The platform grades its own homework; corroborate |
No single method is right for every question. Use platform conversion-lift for a quick read inside one channel, and a geo-holdout when the decision is where to move real budget, because a geo-holdout is the one a platform cannot quietly tilt in its own favor.
How to run your first incrementality test
The mechanics are less intimidating than the vocabulary. A first test looks like this:
-
Write a falsifiable hypothesisName the channel, the expected direction, and the decision. For example: "Branded retargeting drives fewer than 40 percent incremental conversions, so we should cut its budget by half." A hypothesis you cannot fail is not a hypothesis.
-
Define a matched holdoutPick the control: comparable geographies, a percentage of the audience, or a platform-built lift group. The holdout must resemble the treatment group in everything except exposure to the ad.
-
Size it for statistical powerThe constraint is conversions, not spend. Estimate whether each group will accumulate enough conversions to detect the lift you expect. Too few, and even a real effect stays invisible in the noise.
-
Run for 14 or more daysGive the holdout time to make the purchases it would have made anyway. Shorter windows are allowed but riskier, and longer consideration cycles need longer tests.
-
Read the lift and decideCompare conversion rates, calculate incremental lift and iROAS, check significance, and act on the decision rule you wrote in step one, whatever the result.
The one rule that separates a test from a rationalization is pre-committing to the decision in step one. In our CRO work across 7,000+ websites, we consistently see teams design a clean test and then negotiate with the result when the number disappoints, quietly moving the goalposts to protect a channel they had already decided to keep [Omniconvert, 2026].
Nexus by Omniconvert brings the discipline of a controlled holdout to your channel decisions, so you fund the ads that cause sales instead of the ones that merely showed up.
See how it works →Reading the result: what a 28 percent lift means
Take a concrete read. Geo-holdout studies across dozens of direct-to-consumer brands have put median retargeting incrementality near 28 percent, meaning roughly seven in ten attributed conversions were not caused by the ad [reported by adlibrary, 2026]. A separate Meta internal study across 15 advertisers reportedly found only 34 percent of attributed conversions were genuinely incremental. Numbers like these do not mean retargeting is worthless; they mean its dashboard ROAS is inflated two- to three-fold, and the budget beyond the incremental portion is buying conversions you already had.
The brands that plateau at a flat 2x blended ROAS and cannot push past it consistently share one pattern: they scale the channels their dashboard rewards, which are the channels best at claiming credit, and starve the prospecting that actually brings new buyers. The plateau breaks fastest when operators treat incremental lift as the primary unit of budgeting, not attributed ROAS, because only one of the two responds to more spend by producing more customers.
AliveCor used Omniconvert to run a structured A/B testing programme and achieved +21% conversion rate, +5% revenue per visitor, and 94% statistical relevance across their experiments [Omniconvert, AliveCor case study]. The same experimental rigor that produced those reads, a matched control and a pre-committed decision rule, is exactly what an incrementality test applies to media: prove the lift before you fund it.
Incrementality is A/B testing for media spend
This is the bridge that gives the practice its authority. The causal spine of an incrementality test, a treatment group, a holdout, a measured difference, and a significance check, is identical to the spine of a well-run A/B test. The only change is the variable under test: instead of two versions of a checkout, you test spend against no spend. A company that has internalized controlled experimentation on its site is not learning a new skill when it runs incrementality tests; it is pointing an existing one at a bigger budget line.
That is why an experiment library is the natural home for this work. Across 70,000+ experiments spanning 7,000+ websites and 15+ industries, the average controlled test lifted conversion rate 23.2%, and the practice that produced those reads, disciplined holdouts and honest significance thresholds, is the same practice incrementality testing demands of media [CROBenchmark Report 2026, Omniconvert]. Explore is where that experimentation muscle lives, and Nexus by Omniconvert extends it from the page to the media plan, so the lift you measure is mapped to the customer value it creates rather than the credit a platform claims.
Common mistakes to avoid
The recurring errors, and their fixes:
- Too-short windows: A 3-day test rarely gives the holdout time to make its baseline purchases, so the gap you read is noise. Run 14 or more days unless you have a strong reason not to.
- No statistical power: Groups too small to accumulate enough conversions will hide a real effect. Size the test by expected conversions, not by budget.
- Testing everything at once: Changing spend on three channels in one window makes the lift unattributable. Isolate one variable per test, exactly as you would in an A/B test.
- Contaminated control: If your holdout region still sees the brand through organic, email, or spillover, the difference shrinks artificially. Match and isolate the groups.
- Deciding after you see the number: Pre-commit to the action for each outcome. A decision rule written after the result is not a test, it is a justification.
Frequently Asked Questions
Incrementality testing is a controlled experiment that compares a group exposed to your ads against a matched holdout group that is not exposed. The difference in conversions between the two groups is the true incremental lift: the sales your ads actually caused, rather than the ones that would have happened anyway. It is the only method that measures causation instead of correlation, because it shows what would have occurred without the ad.
Attribution assigns credit for conversions that already occurred, usually to whichever ad the buyer touched last or most recently. Incrementality proves which of those conversions the ad actually caused. The gap is large: a campaign can report 3x attributed ROAS while delivering only about 1.5x incrementally, because platforms take credit for buyers who would have purchased regardless. Attribution answers who to credit; incrementality answers what worked.
The four common methods are geo-holdouts, where you pause or vary spend by region and compare treated regions against control regions; ghost ads, which show a placeholder to the control group so you compare people the algorithm would have targeted; PSA or placebo tests, which serve an unrelated ad to the control; and platform conversion-lift studies run inside Meta, Google, or TikTok. Geo-holdouts are the most trusted for total-budget decisions.
Far less than before. In May 2025 Google lowered its incrementality-test minimum from 100,000 dollars to 5,000 dollars, enabled by a shift to Bayesian methods. Geo-holdouts can be run on modest regional spend because they need enough conversions to reach significance, not a large absolute budget. The constraint is statistical power, meaning enough conversions in each group, rather than a fixed spend threshold.
Most tests run 14 days or longer. Platforms allow windows as short as 7 days, but a longer window and adequate sample size matter for statistical confidence, especially for products with longer consideration cycles. The test has to run long enough for the holdout group to accumulate the conversions it would have made anyway, so that the gap you measure reflects real lift and not noise from a short window.
It varies by channel, so there is no universal benchmark. Retargeting often lands at only 20 to 40 percent incremental, because it re-serves ads to warm buyers who were already going to purchase, while prospecting that reaches new audiences can be higher. The point of the test is not to hit a target number but to replace platform-claimed ROAS with an incremental figure you can trust, then shift budget toward the channels that actually cause sales.
Nexus by Omniconvert applies the same controlled-experiment logic that powers incrementality testing across the customer journey, drawing on an experiment library of 70,000-plus tests to design holdouts, read lift, and judge statistical relevance. It maps that lift to segment value and predicted lifetime value, so you learn not only whether a channel caused a sale but whether it caused a profitable one worth funding, instead of trusting a platform dashboard.
A reported 3x ROAS and a measured 1.5x incremental lift describe the same campaign, and only one of them tells you whether to spend more. Incrementality testing replaces the platform's self-interested count with a number you built from a holdout, which is the same causal discipline that made A/B testing trustworthy, now pointed at your media budget. Start with your single largest line item, hold out a matched control, and read the lift. See how a 70,000-experiment library reads causal lift with Explore.
Prove which channels actually cause sales
Nexus by Omniconvert brings the controlled-experiment discipline behind 70,000-plus tests to your media and on-site decisions, so lift is measured against a holdout and mapped to real customer value, not claimed by a dashboard. Stop budgeting against attributed ROAS and start budgeting against causation.