The Anatomy of an Autonomous Growth Engine
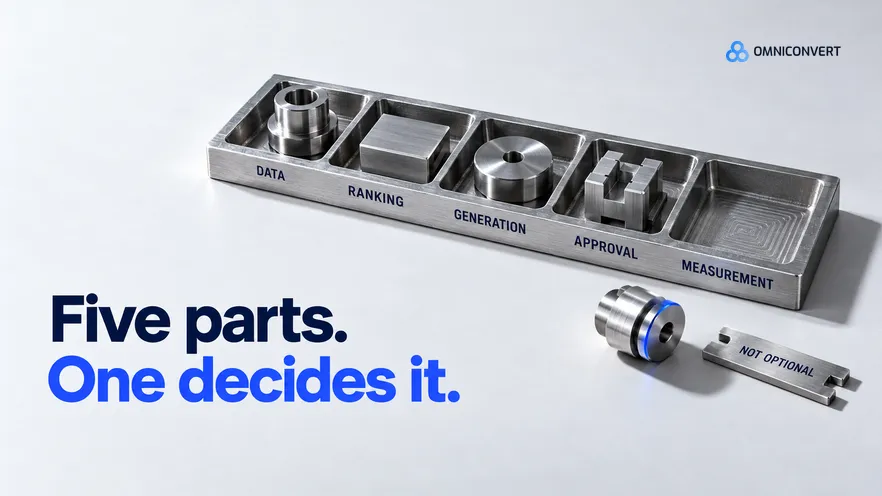
- Five parts: unified data, ranked opportunities, generation, approval, measurement loop.
- Generation is the abundant part and the least valuable on its own.
- Ranking is where the return sits, and most teams have no ranking at all.
- Rank on contribution after costs. A return-on-spend ranking prefers unprofitable work.
- The approval gate is not a limit on autonomy. It is what makes the system adoptable.
Last updated: October 2026
An autonomous growth engine is an industry category, not a product, and taking it apart is more useful than arguing about whether it exists. The category describes a system with five working parts: it unifies commerce data, ranks growth opportunities, generates the work needed to pursue them, routes that work past a person for approval, and measures what happened back into its own ranking. Omniconvert has measured growth and conversion practice across the CROBenchmark dataset of 7,000+ websites in 15+ industries, against 248+ audit criteria, over 13 years in eCommerce, and the thing that stands out when you hold the category against real teams is how unevenly distributed the five parts are. Nearly everyone has the third. Almost nobody has the second.
That imbalance explains a pattern visible across the industry over the past two years: output per marketer rose sharply and results did not follow. More campaigns, more creative variants, more test ideas, roughly the same growth. A system that generates without ranking does not produce more value, it produces more decisions, and decisions were already the bottleneck.
What the autonomous growth engine category actually claims
The term is used loosely enough to be worth pinning down, because two very different claims hide inside it.
The weak claim is capability: the system can do things a person used to do. Generate a campaign, draft creative, segment an audience, propose a test. This claim is true of a great many tools and is not especially interesting, because the work being automated was rarely the constraint.
The strong claim is closure: the system's own output improves its next decision without anybody wiring the feedback by hand. That is what autonomy means here, and it is a much rarer property. A system that proposes a test, has the test run, and then ranks its next proposal differently because of the result is closing a loop. A system that proposes a test and waits to be told what happened is a generator with a good interface.
The distinction matters commercially because the two claims are priced similarly and deliver very differently. If you already have people who can produce campaigns, buying more production capacity moves nothing. If you have no mechanism that makes next quarter's priorities better than this quarter's, that is the gap worth paying to close. We argued the same point from the organisational side in why the growth-team org chart is changing.
The five parts, and which ones are scarce
Taken in the order the loop runs.
1. Unified commerce data. Orders, customers, products, costs, campaigns and site behaviour in one place with consistent identity. Most teams have a version of this and most versions are missing the costs, which is the part that makes the next step possible. A warehouse holding revenue but not cost of goods, fulfilment and returns can rank by revenue and cannot rank by profit.
2. A ranked opportunity set. A list of the things you could do next, ordered by expected contribution. This is the scarce part. Most organisations have a backlog ordered by who asked, how recently it was discussed, or how confident the person proposing it sounded. Converting that into an ordering based on expected value is the single highest-return change available to most growth teams, and it does not require any new software.
3. Generation. Producing the work: campaigns, creative, audience definitions, test variants, briefs. Abundant, improving quickly, and the least valuable of the five in isolation, for the reason above.
4. An approval gate. A person reviewing and authorising before anything reaches a customer. Almost every team has this informally. The question is whether the system is built around it or treats it as friction, which turns out to decide adoption more than any capability does.
5. A measurement loop. Results feeding back into the ranking automatically. The second scarce part, and the one that separates a system that gets better from one that merely runs. Most teams measure results and update priorities in a quarterly meeting, which is a loop with a three-month latency and a human dependency.
| Part | How common | Usual gap | Value if added |
|---|---|---|---|
| Unified data | Common | Costs are missing | High, it unblocks ranking |
| Ranked opportunities | Rare | Backlog ordered socially | Highest of the five |
| Generation | Abundant | Already sufficient | Low on its own |
| Approval gate | Informal everywhere | Treated as friction | Decides adoption |
| Measurement loop | Rare, usually manual | Quarterly, human-triggered | High, it compounds |
Why ranking is the part worth paying for
The uncomfortable thing about ranking is that every team already has one, and almost none of them chose it.
An unranked backlog is not unordered. It is ordered by something: by who asked loudest, by what was discussed most recently, by which channel owner has the most organisational weight, by what is easiest to start. Those are real ordering functions and none of them correlates with expected value.
Where an explicit ranking does exist it is usually built on the wrong measure, and this is the failure worth dwelling on because it is so well disguised. Rank opportunities by return on ad spend and the ranking will reliably prefer work with heavy discounting, broad targeting and low margin, because that work produces impressive channel efficiency and poor contribution. A team following that ranking faithfully will improve every number in its dashboard while the profit and loss statement gets worse, and will have no idea why. We set out the mechanics of that specific trap in why ROAS is the wrong north star.
Ranking on contribution after cost of goods, fulfilment, returns and media is substantially harder. It requires costs in the data layer, it requires accepting uncertainty in the estimates, and it produces an ordering that is sometimes unintuitive. It is also the only ranking that still looks correct a year later. This is why Nexus by Omniconvert prioritises experiments by True Profit rather than by channel return: the ordering is the product, and the measure the ordering uses is the whole argument.
Two external reference points are worth holding beside your own numbers here. Bain and Company's work with Fred Reichheld established that a five percent improvement in retention can raise profits by twenty-five to ninety-five percent, which is why a ranking that ignores retained value systematically under-prioritises the highest-return work available. And the Baymard Institute's checkout research, with roughly seventy percent average cart abandonment, is a reminder that the largest available gains are frequently in work no channel metric will ever rank highly, because the gain does not belong to a channel. The place to start on the value side is customer lifetime value, and on the grouping side customer segmentation models.
The approval gate is a feature, not a compromise
This is the part of the category most often framed as an immaturity, something that will be removed once the technology improves. That framing misreads what the gate is for.
Consider what full automation actually asks of a marketer. Something publishes to a live audience, with their brand on it and their name against the result, that they did not see beforehand. If it goes wrong they are accountable for a decision they did not take. No competent professional accepts that arrangement, and the predictable response is not resistance to technology but a quiet decision to route the important work around the system and keep it for the trivial work. The capability is then irrelevant, because it is not being used where it matters.
Framed the other way round, the gate is what makes the rest adoptable. The system does the work a person cannot do at that volume: holding every cost in view, computing an expected value for each option, keeping the ordering current as results arrive, drafting the thing. The person does the work the system cannot do: judging whether this particular action is right for this brand, this moment and this customer, and taking responsibility for it.
That division is stable because it reflects a genuine difference in capability rather than a temporary gap in one. It is also why Nexus generates campaigns and creative you approve before they go live rather than publishing on your behalf. The constraint is deliberate, and creating an experimentation culture is largely about making that approval step fast rather than removing it.
How to assess any system in this category
- What does the ranking optimise, exactly. Ask for the measure by name. If the answer is revenue, return on ad spend or engagement, you are buying an ordering that will prefer unprofitable work. If the answer is contribution after costs, ask which costs, because the missing ones are where the ordering goes wrong.
- How does a result change the next ranking. Specifically, what happens without a person remembering to update anything. If the answer involves a quarterly review, the loop is open and the system will not improve on its own.
- Who approves, and how long does approving take. A gate nobody can get through is as useless as no gate. Ask to see the review step, and ask how many items a person can realistically clear in an hour.
- What does it do when the data is incomplete. Every real catalogue has products with missing cost data. A system that silently excludes them, or silently assumes a margin, is producing a ranking with a hole in it that nobody can see.
- What would it have told you last quarter. The most useful test available. Run it against a period you already understand and see whether its top-ranked items match what actually worked. Where they disagree, the disagreement is the conversation worth having.
None of those five questions is about what the system can produce, and that is the point. Production is the abundant part of this category. For the broader market picture these systems are arriving into, see the state of DTC growth in 2026, and for the testing discipline the loop depends on, A/B testing is the foundation.
Frequently Asked Questions
It is an industry category rather than a product name: a system that unifies commerce data, ranks growth opportunities by expected value, generates the work needed to pursue them, routes that work through a human approval gate, and feeds the measured result back into its own ranking. Any version missing one of those five parts is a tool rather than an engine, and the gap is usually the ranking or the approval.
Generation, and it is the least valuable of the five on its own. Most teams can produce campaigns, creative variants and test ideas faster than they can decide which are worth running. Adding generation capacity to a system with no ranking produces more work of unknown value, which is why output rose across the industry without a matching rise in result.
Because it is what makes the rest of the system usable by a team that is accountable for the outcome. A system that publishes without approval asks a marketer to accept consequences they did not authorise, and the rational response is to stop using it. The gate is not a safety feature bolted on; it is the thing that lets a person stay responsible for decisions a machine prepared.
Expected contribution after costs, not return on ad spend. A ranking built on revenue or on channel return will systematically prefer discount-heavy, low-margin work because that work looks efficient by those measures. Ranking on profit after cost of goods, fulfilment, returns and media is harder to compute and it is the only ordering that survives contact with a profit and loss statement.
Yes, and many should. The five parts are capabilities rather than products, and a team with a warehouse, a ranking model in a spreadsheet, a generation tool, a review process and an experiment programme already has an engine. What it does not have is the loop closed automatically, which means the ranking only improves when somebody remembers to update it.
Take the category apart and the shopping list inverts. Generation, the part every vendor leads with and every demo shows, is the part you almost certainly already have enough of. The scarce parts are the ranking that decides what deserves doing and the loop that makes the ranking better over time, and those are the two that nobody demos because neither produces anything visible in a thirty-second clip. So when you assess any system in this category, ask three questions in this order. What does it rank on, and does that measure survive contact with your profit and loss statement. What happens to the ranking after a result comes in, and does that happen without someone remembering. And who approves before anything reaches a customer, because a system that answers nobody is a system your team will stop using within a quarter, whatever it can produce.
See where the ranking comes from
Nexus by Omniconvert unifies commerce data, prioritises experiments by True Profit, and generates campaigns and creative you approve before they go live.